Navier–Stokes, Scaling Laws, and Peak Tokens
What if the real constraint on AI isn't energy or money, but tokens — and the race to the frontier is built to cannibalize itself?
Much has already been said about the OpenAI Navier–Stokes affair — about the credibility of the method itself (does the model actually reason, or is this brute force dressed up as insight), and about the credit dispute with the mathematicians who were working the same problem. One detail, though, is worth dwelling on longer than the rest of the coverage has: OpenAI's own admission that "while unlikely, [it] cannot rule out that de-identified data derived from their usage of our products helped improve our models."
Behind that sentence sits a fairly simple fact: any AI model needs good data to keep improving. The public conversation about AI's limits keeps circling around an energy wall, or a valuation bubble. But what if the real binding constraint is something narrower and more specific — tokens — and what if, for this particular resource, the race to the frontier is set up to cannibalize itself?
1. Data is all you need
At first order, progress in these models has depended on scaling two things together: compute and training tokens. Very roughly speaking, for each additional parameter, 20 additional tokens are needed.
This arithmetic quickly exhausted the internet. Current models are already trained on the whole internet. It's worth noting, in passing, that the other commonly discussed constraint — energy and compute infrastructure — is the one the industry actually knows how to throw engineering at, however extreme: Google and SpaceX are jointly developing Project Suncatcher, orbital data centers running on continuous solar power, targeting deployment as early as 2027. There is, notably, no equivalent engineering fix for a shortage of genuinely new ideas. You cannot launch a satellite to go fetch a thought that doesn't exist yet.
2. The law of receding tokens
With the open internet drained, the hunt has moved to other reservoirs: open data commons that were never built to withstand this kind of load. Wikimedia has documented a 50% surge in bandwidth demand on Wikimedia Commons driven by AI crawlers; The Register names Meta and OpenAI specifically as the worst offenders. The same pressure is reported anecdotally around other open infrastructure — OpenStreetMap and Zenodo among them — maintainers describing a need to defend against "excessive automation" alongside legitimate use.
But the open commons aren't the only reservoir left to mine. The Navier–Stokes episode reveals the next one: users' own prompts. If interactions with a model can measurably improve it, then prompts are training data too — original, unpublished, often more valuable per token than anything left on the open web, precisely because they capture reasoning that has never been written down anywhere else. The question this opens isn't legal so much as reputational: once people understand this is happening, how will it be received?
3. The clock is ticking
If the pool of good prompts is the last frontier, it's also a strikingly fragile one, for at least two reasons.
First, an eviction effect: people with genuinely original ideas may simply stop feeding them to a tool, once the Navier–Stokes precedent is out there. This isn't a hypothetical reaction — the mechanism has already been measured elsewhere. After the Snowden revelations, Jon Penney's study of Wikipedia traffic found a measurable drop in visits to sensitive topics, driven purely by the awareness of being watched, without any actual enforcement action ever taking place. There's no reason to expect researchers and domain experts to behave differently once they suspect their brainstorming sessions might be harvested.
Second, a structural response: the growth of self-hosted, open-weight models will likely absorb a growing share of exactly this kind of high-value brainstorming, run locally and never reaching Anthropic's or OpenAI's servers at all.
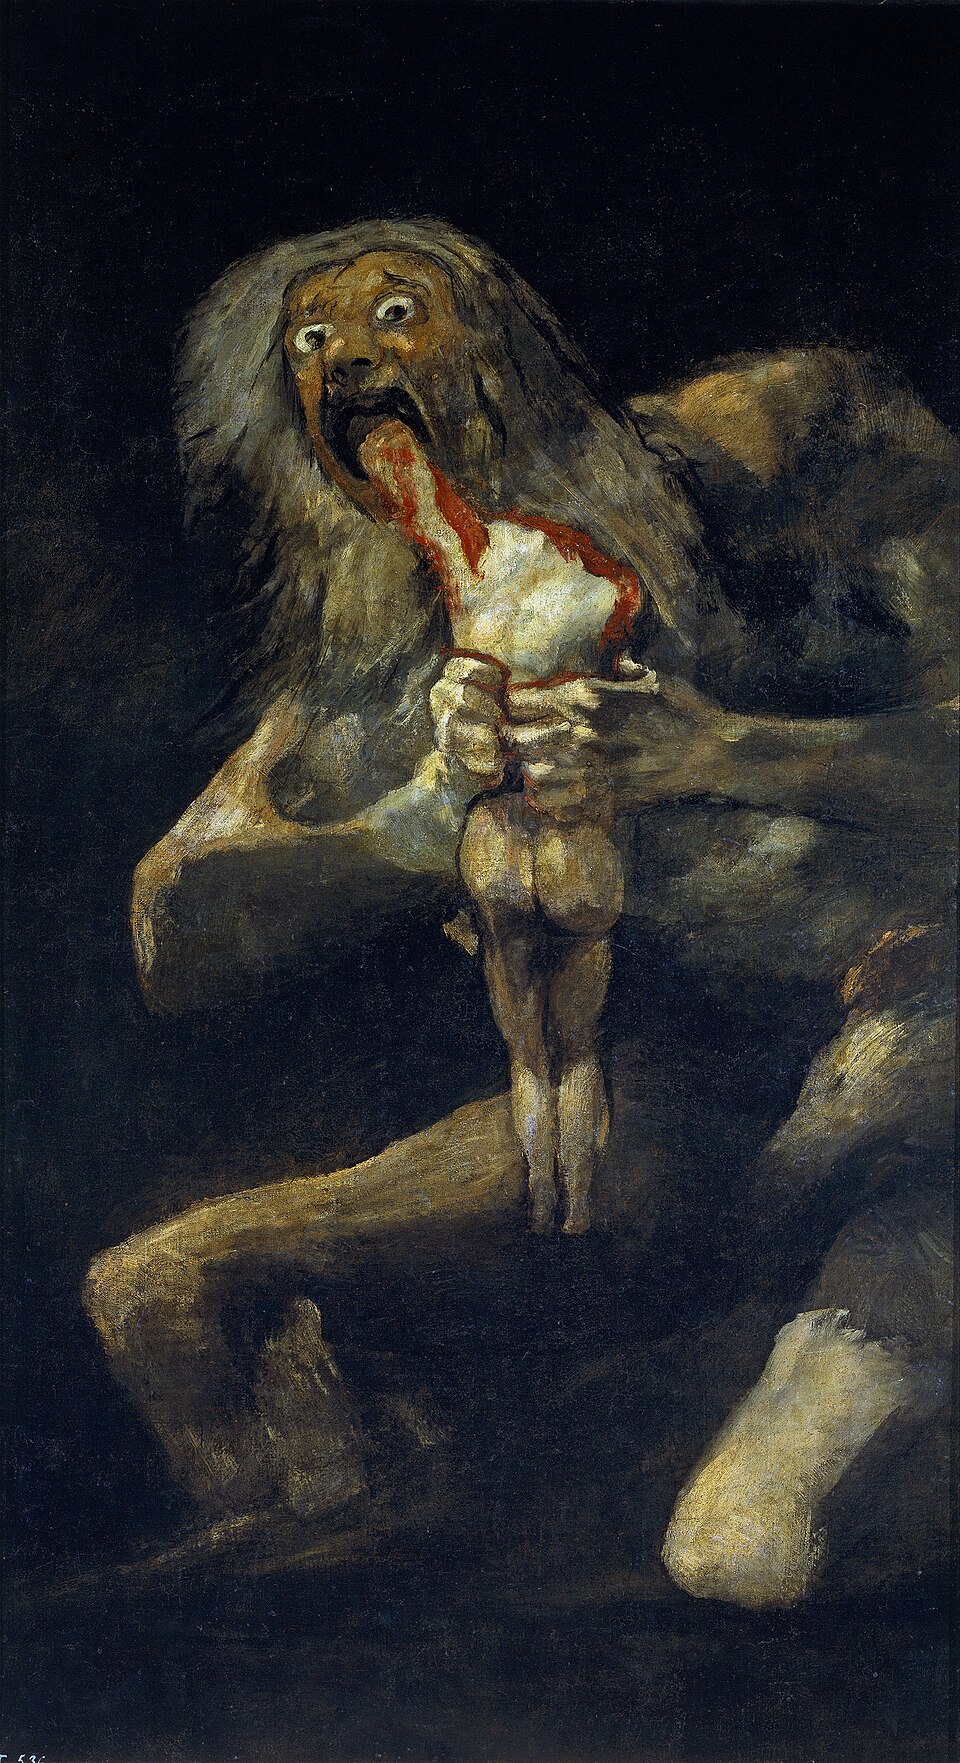
OpenAI's celestial naming scheme is well chosen, incidentally — Terra, Luna, Sol. A fitting next name for GPT-6.1 might be Saturn: the Roman god who devoured his own children. More fundamentally, though: it's worth asking whether the deposit of usable data needed to train the next generation of these models might run dry before the data centers meant to train them have even finished being built.
Sources
- OpenAI — On the Navier–Stokes Millennium Prize Problem
- Reconciling Kaplan and Chinchilla Scaling Laws (arXiv)
- PBS NewsHour — AI gold rush for chatbot training data could run out of human-written text as early as 2026
- Wikimedia Diff — How crawlers impact the operations of the Wikimedia projects
- TechCrunch — AI crawlers cause Wikimedia Commons bandwidth demands to surge 50%
- The Register — AI crawlers and fetchers are blowing up websites, with Meta and OpenAI the worst offenders
- State of the Map 2026 — "Running OpenStreetMap.org in the Age of AI" (Grant Slater)
- The Conversation — Data centres in space: will 2027 really be the year AI goes to orbit?
- Data Center Dynamics — Project Suncatcher
- The Intercept — Mass surveillance breeds meekness, fear, and self-censorship, new study shows (Jon Penney)